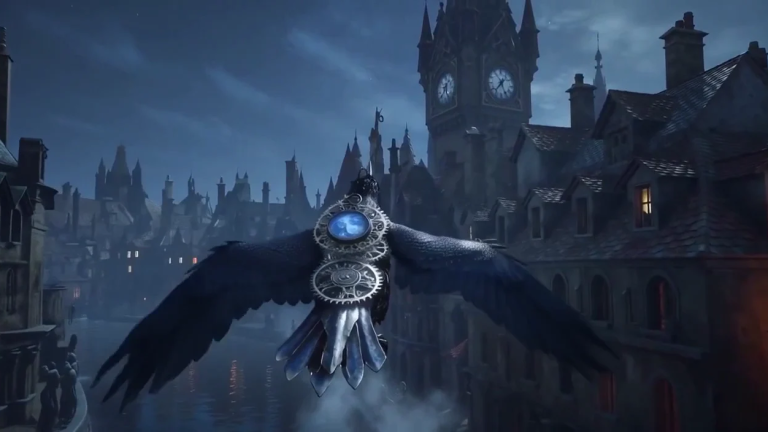
Image: Tencent Hunyuan, frame from the Hy-Nomas “clockwork flight” gallery clip, via the Hy-Nomas project site
Tencent Hunyuan has released Hy-Nomas, an open video model you steer while it generates. You write an opening scene, then keep sending new text instructions or camera moves, and each new segment of video continues the same world. The weights, inference code and training code are on GitHub under the Apache 2.0 license, and there is an online demo if you would rather not install anything.
What Hy-Nomas Actually Does
Most video models work like a one-shot request: prompt in, clip out, and if the third second goes wrong you start over. Hy-Nomas is built around turns. According to Tencent’s model card, it “generates a world one video segment at a time, allowing users to introduce objects, change styles and scenes, describe actions, or control the camera as generation continues.” A persistent memory carries context from one segment to the next, so the raven you introduced in turn one is still the same raven in turn four.
You can steer with words, with a camera trajectory, or with both alternating inside one run. Output is 1280 x 720 at 24 fps, generated with a distilled eight-step setup.
The 60-Second Demos
The best way to judge it is the project site’s gallery, where each clip is a 60-second, five-turn journey with the prompts shown. One follows a clockwork raven, a black-and-silver automaton with a blue moon-phase dial in its chest, through a moonlit Gothic city. Turn one sets the scene. Later turns have it hop along a bridge railing, fly inside a clock tower between giant pendulums, peck the dial so every clock in the city runs backward, and finally climb a spire as the city turns into a rotating mechanical astrolabe. (The gallery prompts are written in Chinese; that summary is my translation.)
Every turn also repeats the same camera instruction: a steady third-person follow shot from behind or slightly to the side, keeping the full silhouette of the subject in frame. That repeated line is a useful habit to steal. Models that drift between close-up and wide are a pain to cut together, and telling the model to hold one coverage style for the whole run is cheap insurance.
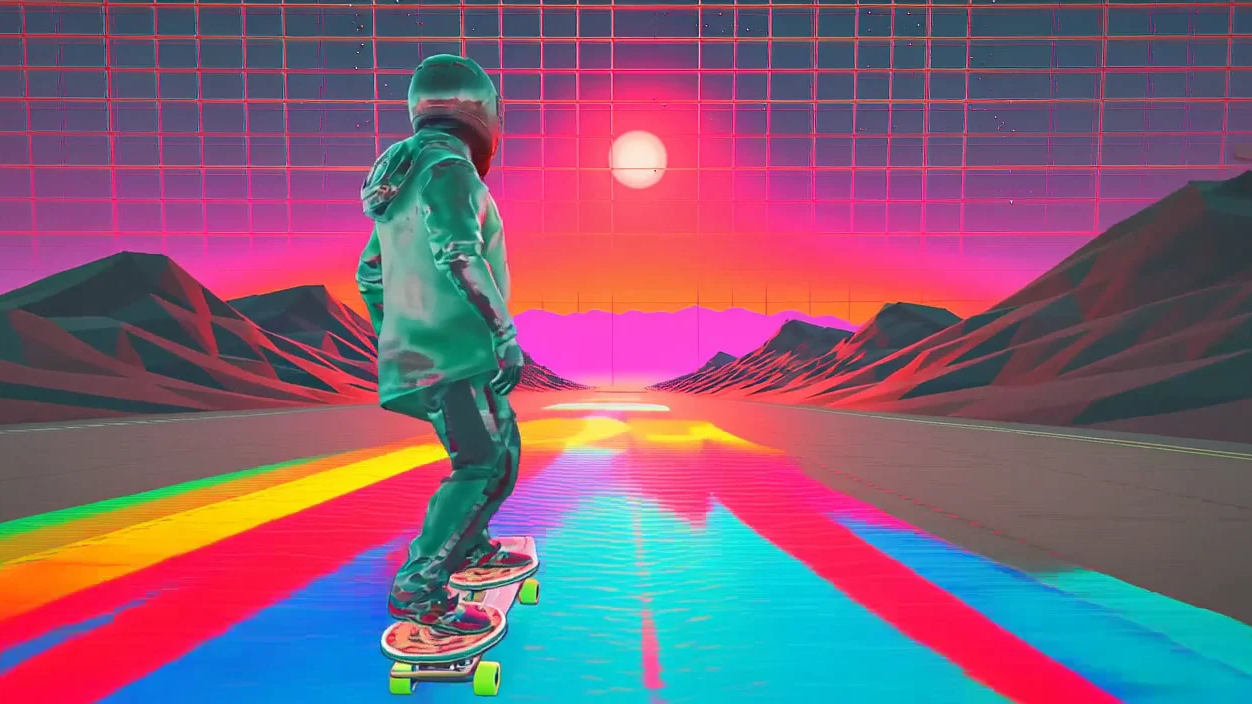
Photo: Tencent Hunyuan, frame from the Hy-Nomas “neon skate” gallery clip, via the Hy-Nomas project site
How You Can Run It
Tencent’s README says Hy-Nomas runs on a single GeForce RTX 4090 using an INT8 model, an INT8 memory cache, an FP8 decoder and CPU offloading, so it is a real option for a workstation and not only a data center. The standard configuration is built for multi-GPU sequence parallelism, and ComfyUI Wiki puts that at eight GPUs. Docker is the recommended install route.
Speed is where the 4090 path gets tested. The developer of a community ComfyUI port reports that on an RTX 5090 a three-second turn at 1280 x 704 takes about 21 seconds. That is slow enough to feel like a directing session rather than a render, and fast enough to iterate. The same port adds an interactive node where you fly the camera with WASD and the mouse, and the move is recorded and played back in the next turn.
Tencent also ships two LoRA adapters: a Cinematic one meant to lift visual quality, and a robotics one trained on a real robot-arm dataset. The training code is included, so studios with a lot of GPUs can fine-tune on their own footage.
What to Be Careful About
This is a world model, not a finished-shot machine. Two limits matter to editors. First, the community port’s README states there is no image-to-world input: every world starts from text, so you cannot hand it your keyframe or your product shot. Second, the technical report is still marked “coming soon”, so there is no independent, published evaluation yet beyond Tencent’s own 280-case benchmark.
The gallery is also curated by the people who built the model. Treat it as the ceiling, not the average. Expect to spend turns steering back from drift, and expect the 720p output to need upscaling and a proper grade before it sits next to camera footage.
Where It Fits in an Edit
The realistic jobs are previs, music-video interludes, game-style fly-throughs and background plates for motion graphics, where an AI look is part of the point. Bring the segments into Premiere Pro or DaVinci Resolve, match them to your timeline frame rate, and cut on the turn boundaries, since those are the natural seams.
Clean AI video also tends to look too smooth. Laying a real scanned grain over the whole sequence, such as the real-film-scan overlays in Grainzilla’s free downloads, is the quickest way to tie generated shots together and take the plastic edge off. We cover why scan quality matters in our film grain comparison.
The Takeaway
Hy-Nomas is interesting less for its resolution than for its workflow: you direct a shot as it unfolds, the way you would talk a camera operator through a take. Open weights mean someone will wire it into an editor soon. Until then, it is a strong toy and a promising previs tool, and a reminder that the cut still has to happen in the edit.
Sources: Tencent-Hunyuan/Hy-Nomas on GitHub; tencent/Hy-Nomas on Hugging Face; Hy-Nomas project site and gallery, Tencent Hunyuan; ComfyUI Wiki, Hy-Nomas; Nynxz, ComfyUI-HyNomas on GitHub.